MCP and A2A Are Not Integration
Why your integration team is the wrong owner for your agentic capability
Somewhere in your organisation right now, someone is putting MCP in front of an existing API catalogue and calling it an agent platform. It is the obvious move. The APIs already exist, they are already authenticated, already logged, already monitored, and wrapping them is a fortnight of work rather than a redesign. I understand completely why it happens. It is also, in a fair number of cases, going to turn out to be an expensive mistake.
For thirty years enterprise integration has rested on one straightforward assumption: systems need to exchange data. So we build APIs. Customer gets getCustomerById, getCustomerByName, getCustomerByIdentifier, getCustomers, searchCustomers, and then we wrap the lot in authentication, authorisation, gateways, logging, monitoring and rate limiting. It works. It has worked for a very long time. It works because the consumer is an application.
It becomes a completely different proposition when the consumer is a language model.
The problem is not the API. It is the consumer.
A traditional application does not reason about the APIs available to it. A developer picks one and writes the logic. The choice happens once, at design time, in someone's head, and the cost of having five near-identical customer lookups is close to zero because nobody has to think about them at runtime.
An agent is different. Hand it this:
getCustomerById
getCustomerByName
getCustomerByIdentifier
getCustomers
searchCustomers
getAccount
getInvoices
getInvoiceById
...
and you have just made your API catalogue part of the model's reasoning environment. Every one of those definitions is now something the model carries and considers. That has a measurable price, and the numbers are worse than most people assume.
Anthropic's published work on advanced tool use puts real figures on it. In its reported evaluation, loading a large tool library upfront consumed roughly 77,000 tokens before the model had done any useful work at all. Routing the same library through its Tool Search Tool brought that down to about 8,700 tokens, an 85% reduction that preserved 95% of the context window.1
The part that should genuinely worry an architect is that this was not only a cost problem. Tool-selection accuracy on the same evaluations improved from 49% to 74% for one model and from 79.5% to 88.1% for another once the catalogue was taken out of the upfront context.1 A bloated tool surface does not merely cost you money. It makes the agent measurably worse at choosing the right thing to do.
Anthropic's operational documentation says the same thing more plainly: tool definitions and accumulated tool results consume the context window, and tool search is the recommended remedy once a toolset grows past roughly 20 tools.2 Twenty. Most enterprise integration catalogues clear that before lunch.
And the economics compound, which is the bit that gets missed. If an agent takes ten reasoning turns and every turn carries the catalogue, you have not paid for your API surface once. You have paid for it repeatedly, in every turn, in every conversation, across every user. At enterprise volume that stops being a billing curiosity and becomes an architecture problem.
The agent does not want your API catalogue
An agent does not actually care whether customer information arrives via getCustomerById or searchCustomers, or whether it is stitched together from three different backend systems. What it wants to express is considerably simpler:
I need customer information.
That gap, between the operation and the intent, is the whole distinction between an integration interface and an agent capability. Rather than exposing every implementation operation, you expose the meaningful capability and let something behind the boundary work out how to satisfy it:
External LLM
     |
     |  MCP
     v
Customer capability
     |
     |  A2A
     v
Customer Agent
     |
     +-- getCustomerById
     +-- getCustomerByName
     +-- searchCustomers
     +-- getAccount
     +-- getInvoices
The external model sees one capability. The Customer Agent owns the mess. That is a different abstraction, not a thinner wrapper over the same one.
So when is it MCP and when is it A2A?
The protocols are clearer about this than most of the commentary around them. The A2A project states it directly: "MCP is for agent-to-tool communication: it standardizes how an agent connects to its tools, APIs, and resources to get information", while "A2A is for agent-to-agent communication", letting independent agents discover each other, delegate tasks and share results. Its guidance is to use MCP to equip an individual agent with the tools it needs, and A2A to let that agent collaborate with other agents across frameworks.3
So in practice. Put yourself in the position of an agent, part-way through a job, that needs something it does not have. You are the one doing the asking. The question is not how you word the request. It is what is sitting on the other end of it.
| What you need | What can answer it | So you call it over |
|---|---|---|
| Customer 123 | A tool. You name the record and it hands back exactly that, because you already know what you want. | MCP |
| Whatever is going on with customer 123 | An agent. Nobody can name the records in advance, so something has to decide where to look and when to stop. | A2A |
| Invoice 4471 | A tool. One identifier in, one document out. | MCP |
| Whether the invoice history explains this anomaly | An agent. It has to form a view, and it may need several passes to get there. | A2A |
| The rows this query returns | A tool. You wrote the query, so you have already done the thinking. | MCP |
| Whether our evidence supports the proposition | An agent. Deciding what counts as evidence is the job, not a lookup. | A2A |
A confession about that table, because it is relevant. This is the third time I have rewritten this section. The first two attempts were wrong in the same way: I wrote lines like "get customer 123 is MCP", which quietly turns a protocol into a category of sentence. It is not one. It is the channel to a particular kind of responder. Every time I compressed the idea, the compression itself introduced the error, and people came back confused. They were right to.
That is worth noticing rather than hiding, because the failure mode is the same one this whole article is about. When a section resists being written three times, something is being conflated, and here it was the shape of the request being mistaken for the choice of protocol. If it is that easy to garble in prose by someone who does the work, it is going to get garbled in your design review too.
So read the table by its middle column, which is the only one that actually decides anything. Notice what happened to the left column as a side effect: on the MCP rows you had to state precisely what you wanted, and on the A2A rows you stated a goal and left the method alone.
That difference in precision is not the test. It is the consequence. A tool does exactly what it is told and cannot work anything out, so you are obliged to be exact with it. An agent can work out the method, so you are free to hand it something open-ended. You are not choosing a protocol because your sentence is short or long. Your sentence ends up short or long because of what is answering it.
MCP means you have to say what to fetch. A2A means you get to say what you want and let something else decide what to fetch.
None of this depends on whether the system underneath is Salesforce, SQL, SAP or a Lambda function. It depends on whether the thing on the other end has to think.
One clarification, because this is where most of the confusion lives and I have watched it derail a design review. That rule governs the thing you are calling. It does not decide the protocol at your own front door.
The protocol at your boundary is set by what your consumer speaks. If the thing reaching for you is Claude Desktop or ChatGPT, it is an MCP client and not an A2A peer, so MCP is the only door available regardless of how much reasoning happens once the request is inside. If the thing reaching for you is another organisation's agent, A2A is on the table. That is a fact about your consumer, not a judgement about the work.
Two decisions get collapsed into one constantly. Which protocol you speak is largely dictated to you. What granularity you expose is entirely yours, and it is the one that costs you money.
Keep them apart and the rest of this gets much easier. Granularity is orthogonal to protocol: exposing four meaningful capabilities rather than five hundred implementation operations is the right call whether you are serving them over MCP, over A2A, or over something that has not been invented yet.
Where traditional integration thinking gets expensive
The integration team's instinct is to expose what already exists, and that instinct is normally correct. We have APIs, so we wrap the APIs. We have 500 operations, so we publish 500 tools. We have a customer service, so it becomes an MCP server. Nothing there is technically wrong. Architecturally it can be quite costly, because the model now reasons about your implementation rather than your capability.
Nor is it solved by hiding 500 tools behind one endpoint. The model still has to discover and reason about a large catalogue. Tool search genuinely helps, and the numbers above show how much, but note what Anthropic actually says about it: it "trades a small amount of latency (one extra turn to look up a tool) for a large reduction in baseline context usage".2 Their recommended sequence is prompt caching from day one, tool search past roughly twenty tools, context editing once conversations run long.2
Read that list again, because it is a list of context-management techniques. Every one of them is a way to make a large surface cheaper to carry. None of them answers the question of what abstraction you wanted the model reasoning over in the first place.
That is an optimisation. It is not an architecture.
The agentic architecture is a different shape
The better question is not "which APIs do we expose". It is "what should an external reasoning system be able to ask us to do".
Answered properly, it might see four things:
investigate
deconstruct_question
collect_evidence
manage_evidence
Behind those sit agents, services, APIs, databases and tools, in whatever tangle history left you. The external model does not need to understand any of it.
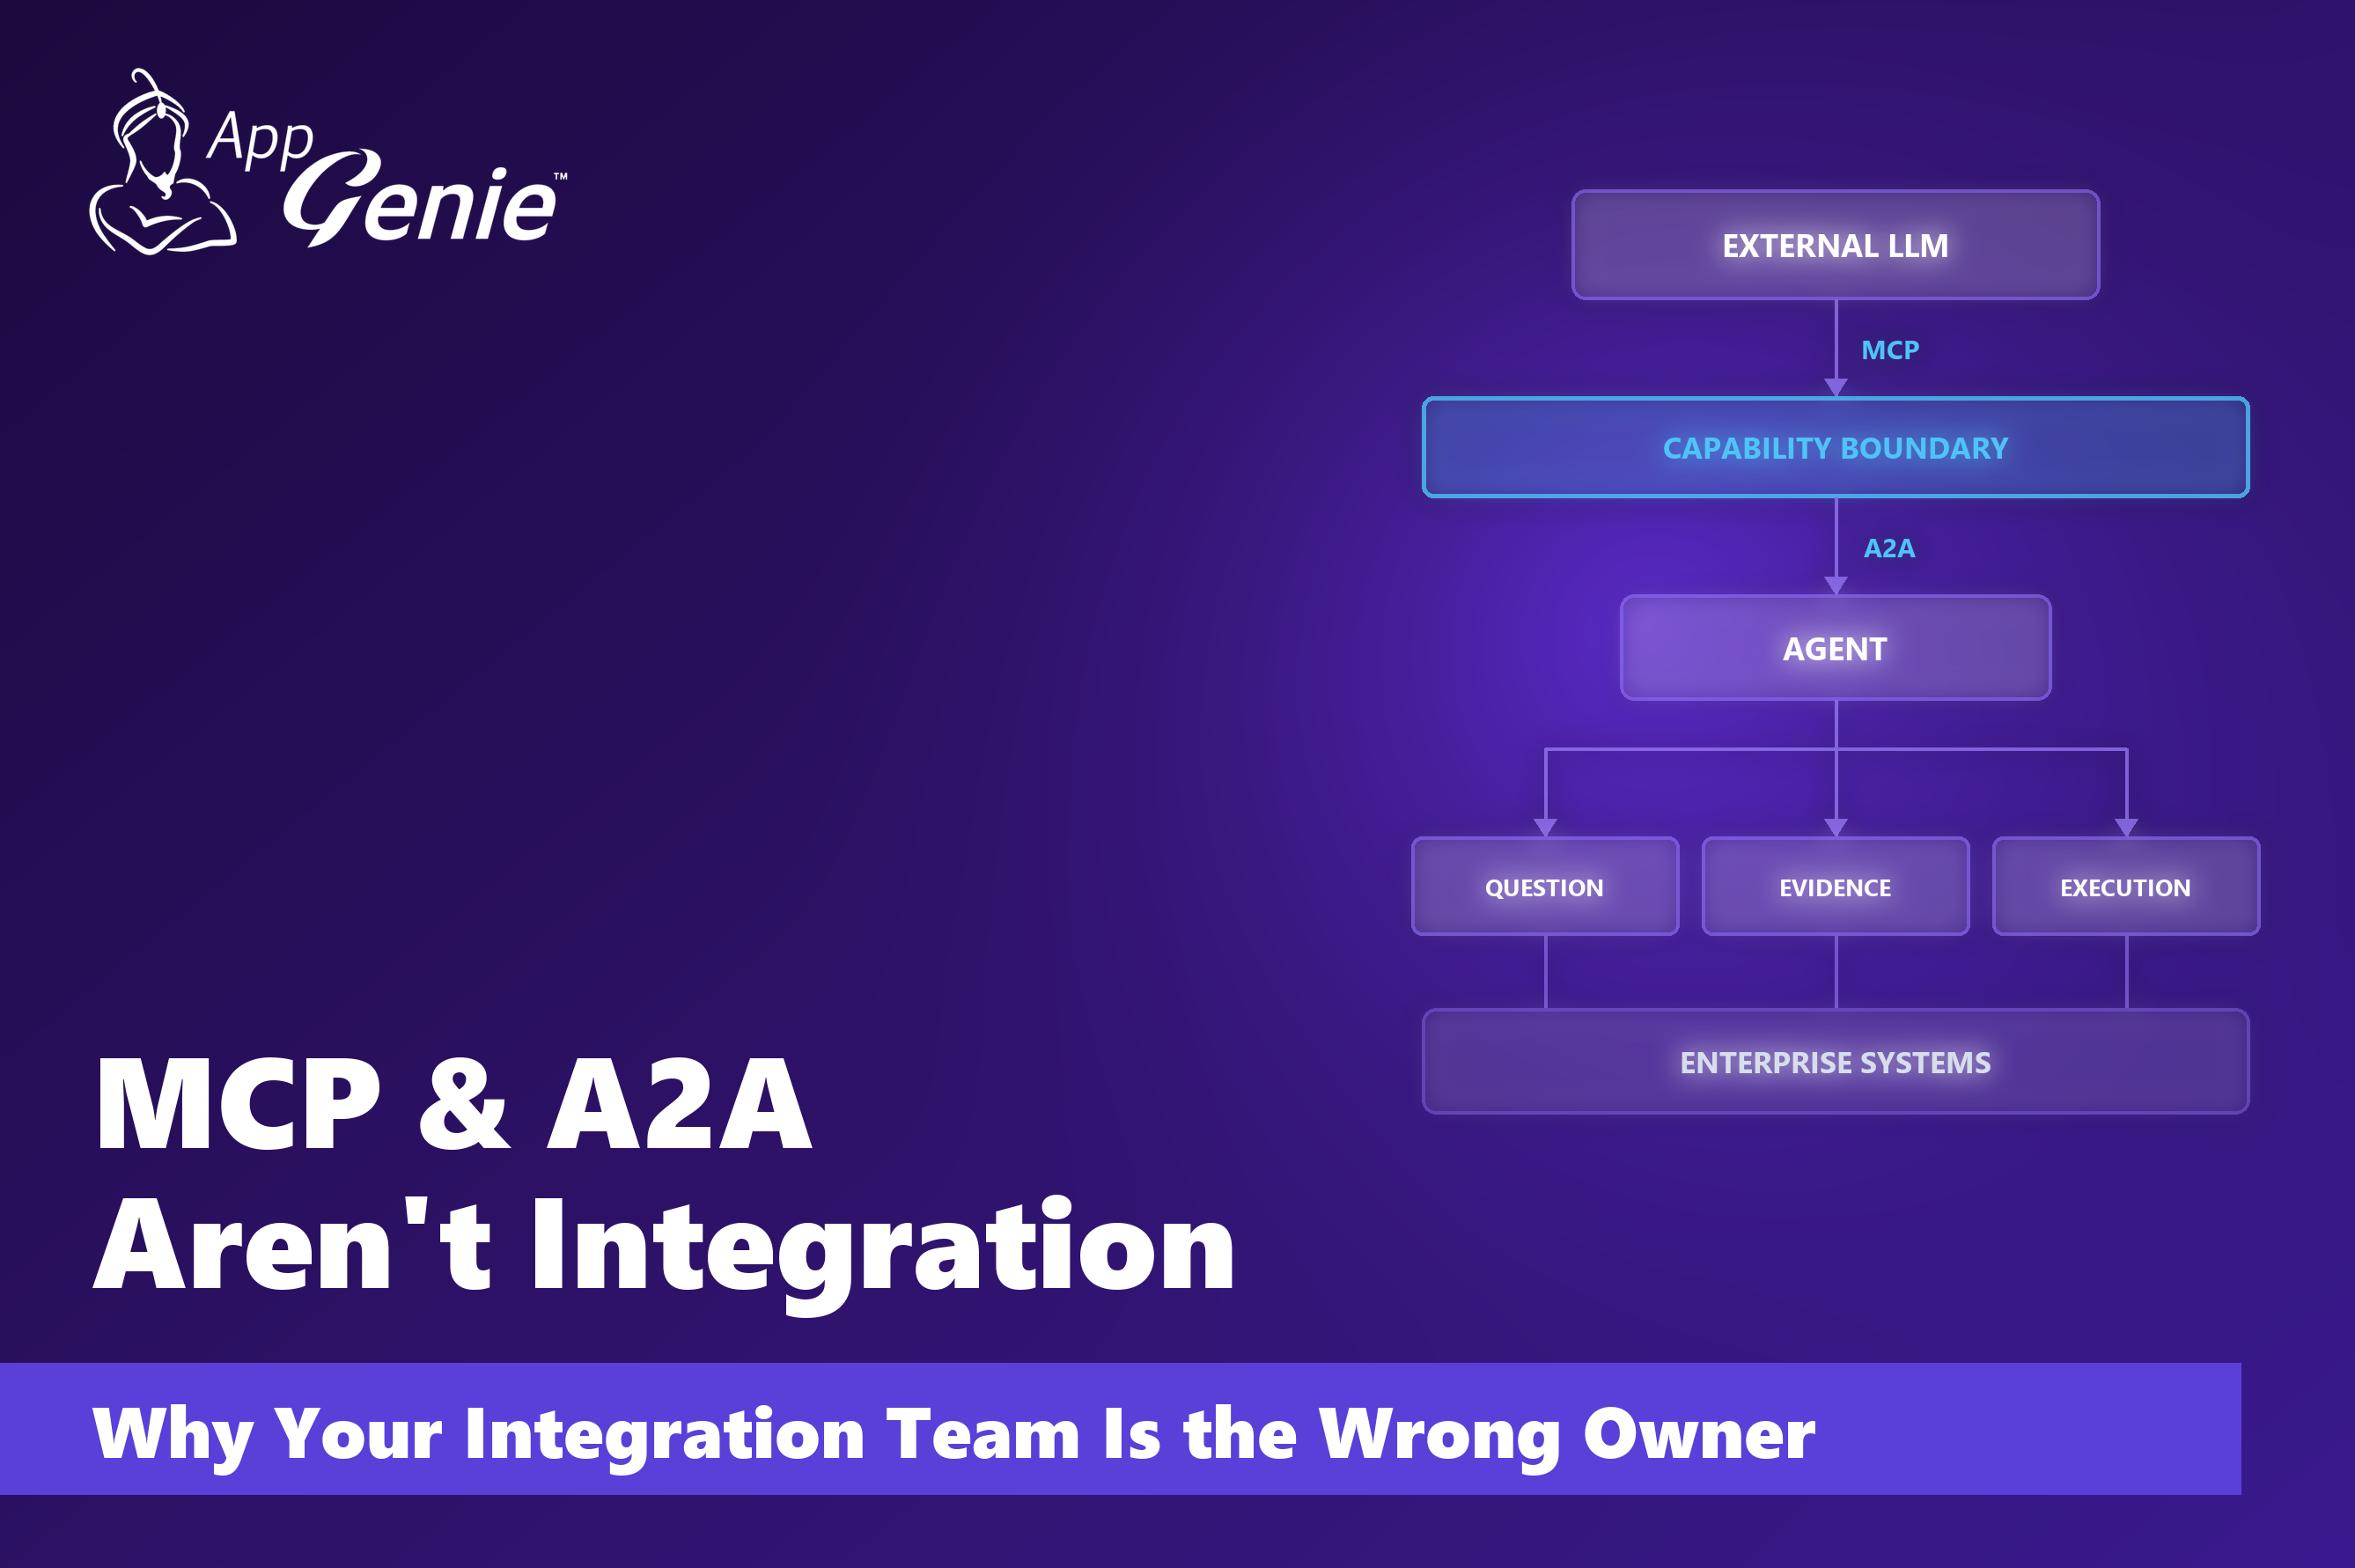
              External LLM
                    |
                   MCP
                    v
         +---------------------+
         | CAPABILITY BOUNDARY |
         +---------------------+
                    |
                   A2A
                    v
                  Agent
                 /   |   \
                /    |    \
         Question Evidence Execution
            Agent   Agent    Agent
                \    |    /
                 \   |   /
             Enterprise systems
In that topology MCP is the capability boundary and A2A is the delegation boundary, and it is worth being explicit about why rather than treating it as a law. MCP sits at the top because the external consumer is an MCP client, which is what most of them currently are. A2A sits underneath because the things on the other side of that line are genuinely agents, reasoning and holding state, rather than tools. Both choices follow the same rule applied to different counterparties.
Turn the topology around and the protocols move with it. If the external consumer were another organisation's agent, A2A would belong at the front door and the arrangement would look like the one the A2A documentation describes directly: agents talking to each other over A2A, each using MCP inwardly for its own tools. The layering is not a property of capabilities. It is a property of who is standing on each side of the boundary.
Either way, the enterprise systems go back to being implementation details, which is what they always should have been.
This is why it is not simply the next integration technology
Integration asks how System A calls System B. Agent architecture asks what an external reasoning system should be allowed to perceive, request and delegate. Those are not the same question. The first is about connectivity, contracts, security and reliability. The second adds context, inference, decisioning, autonomy and cost.
Once tool descriptions become part of the model's reasoning environment, your interface design directly drives inference economics and agent behaviour. Your API catalogue has stopped being purely an integration asset. It is now part of your AI architecture, whether anyone has said so out loud or not.
The cost model changes underneath you
With conventional integration, a badly designed API costs you an extra network call. With an agent, a badly designed capability costs you more context, which means more tokens, more inference, more tool-selection decisions, more latency, and more opportunity for retries and wrong calls, each of which triggers more inference. The failure mode is multiplicative rather than additive.
This is not a theoretical concern. Gartner predicted in August 2026 that AI inference cost per agentic workflow will rise more than fivefold through 2028, and named the underlying dynamic the Inference Paradox: better unit economics encourage bigger models, more tokens and more elaborate workflows, so total cost can climb even while the price per token falls.4
Which means the cheapest API is not necessarily the cheapest agent capability. The cheapest architecture is the one that minimises how much unnecessary reasoning the model has to perform, and you decide most of that at the boundary.
Which is why ownership matters
Your integration team should own the APIs. They should own the pipes, the connectivity, the contracts, the authentication, the resilience and the integration governance. They are good at it and nobody else should be doing it.
They should not automatically own the design of the agent capability boundary, because the question they are trained to ask is "which APIs do we expose". The question that matters here is "what does the agent need to know, and what work should it be able to hand over". Those produce very different designs, and only one of them has a token bill attached.
The mistake is taking an existing integration architecture and putting MCP in front of it. The opportunity is to design a capability architecture for reasoning systems, and then use MCP and A2A appropriately behind that boundary.
The decision is actually quite simple
Two questions, asked in order. First, what am I reaching for? If it is deterministic and bounded, with a well-defined input and output, that is a tool and MCP is probably right. If it needs interpretation, multiple actions, state, iteration, specialist knowledge, long-running execution or an independently managed reasoning process, that is an agent and A2A is probably right.
Second, and separately, what granularity am I publishing at my own boundary? That answer should be capabilities rather than operations, and it does not change based on which protocol carries them.
The protocols are complementary rather than competing, which is what makes both questions answerable at once. The A2A documentation describes the arrangement plainly: an agent talks to other agents over A2A while using MCP internally for its own tools and resources.3 Which gives a mental model worth keeping:
MCP exposes what an agent can use. A2A exposes what an agent can delegate.
Why we care about this
We run an MCP server in production, so this is not an abstract preference. When we built the AppGenie Compliance MCP we deliberately exposed two tools rather than a shelf of them, because the useful capability is "tell me what applies to this piece of delivery work and what evidence it needs", not forty separate lookups against a standards corpus. The catalogue would have been easier to build. It would have been worse to use, and every consumer would have paid for the difference on every turn.
That is the discipline this comes down to. Design the boundary for the consumer you actually have, and in this case the consumer reasons, costs money per token, and gets less accurate the more choices you put in front of it. Wrapping the catalogue is faster today. It pushes the cost onto every future call, and onto the accuracy of every decision the agent makes.
Get the boundary wrong and the price is not one more API call. The price is making the model reason about your entire enterprise integration catalogue every single time it tries to get anything done.
- Introducing advanced tool use on the Claude Developer Platform - Anthropic. Source of the 77K to 8.7K token figures, the 85% reduction, and the tool-selection accuracy improvements.
- Manage tool context - Claude Platform documentation. Source of the 20-tool threshold, the latency tradeoff and the recommended sequence.
- A2A Protocol - the A2A project. Source of the agent-to-tool versus agent-to-agent distinction and the complementary architecture.
- Gartner Predicts AI Inference Costs Per Agentic Workflow Will Increase More Than Fivefold Through 2028 - Gartner press release, 17 August 2026.